
Set your data boundaries
Choose where models can run and which destinations each workflow may use, including its fallback paths.
Aventail™ is an integrated AI inference platform combining a built-in inference engine, model deployment across hardware, and policy-based inference routing.
Run supported models on your devices, servers and private cloud, with access to approved external AI providers. Deploy, run and manage inference through one platform, without separately assembling and maintaining a model-serving stack.
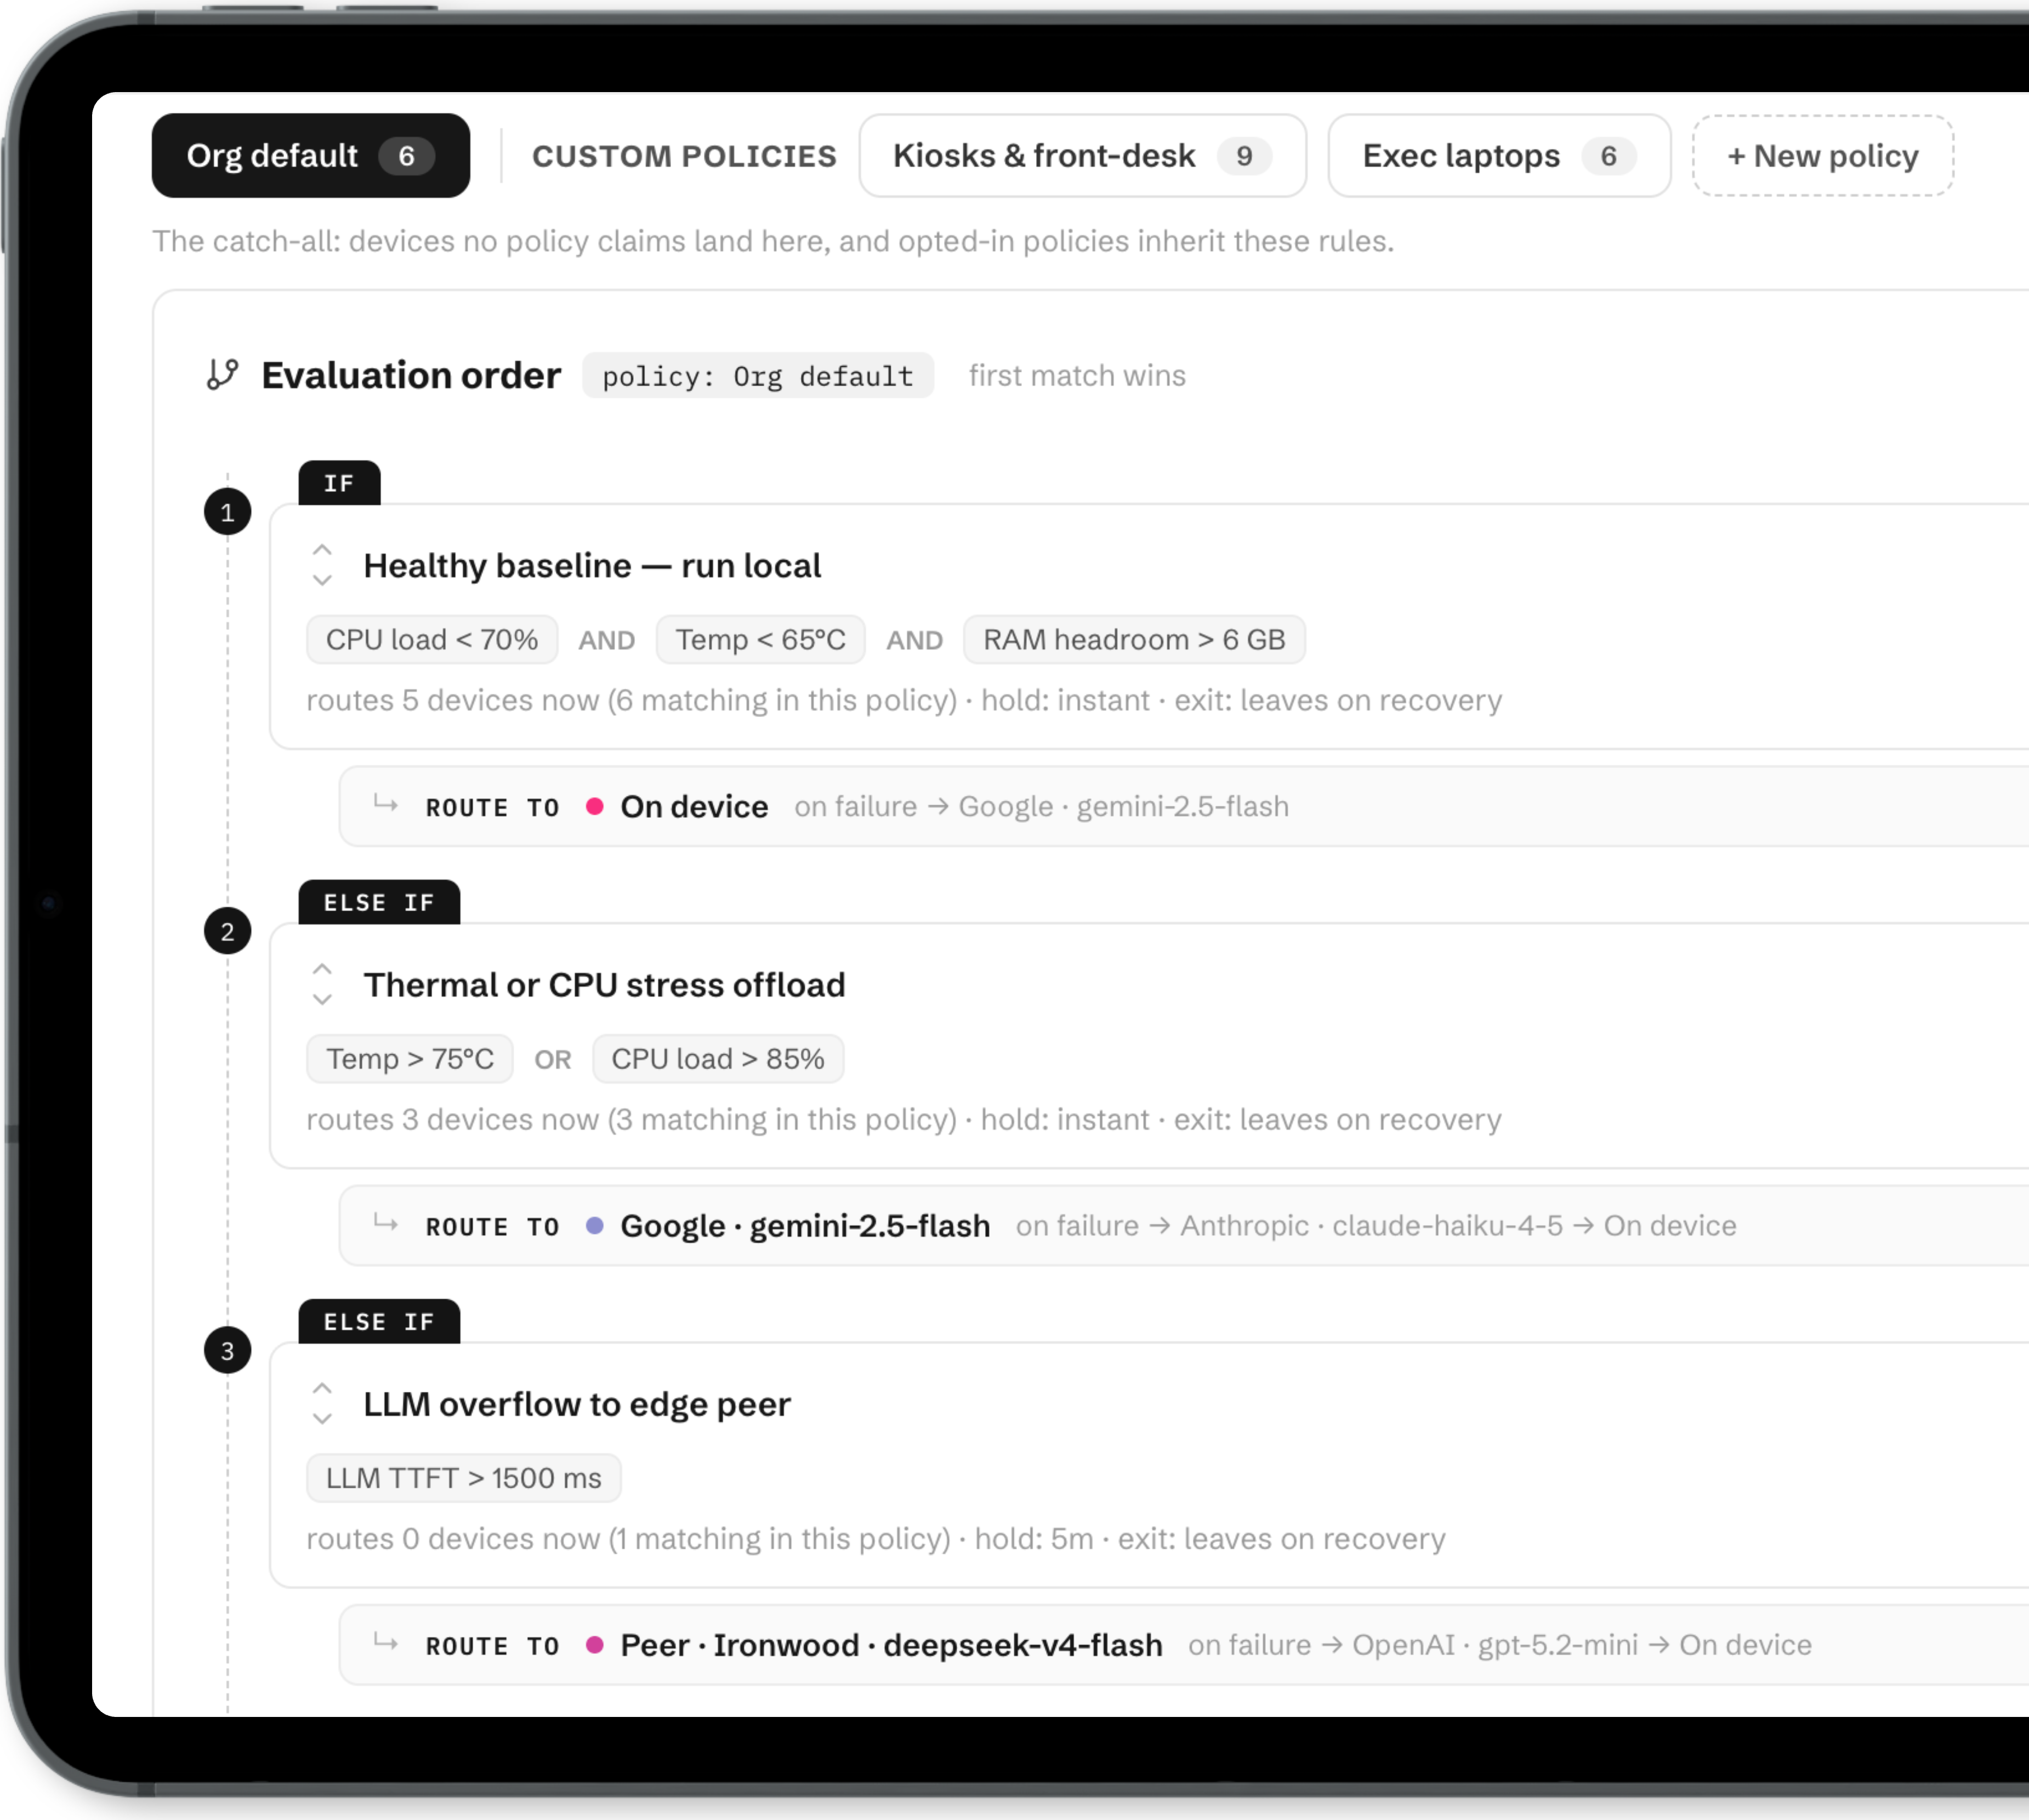
Get the desktop app, or install the runtime from your terminal.
Secure on-device content-aware routing. Aventail™ Link evaluates the query, model fit, device conditions and your organisation’s requirements, then applies your rules to choose where inference runs.
Interactive illustration. Example signals and infrastructure; no query is sent.
Help me with this request.
Aventail™ Link will evaluate the query and constraints locally. No query leaves this illustration.
Example properties only. Default order: this device, another machine, on-premises server, private-cloud machine, provider server, frontier API. Lower-latency preference order: this device, another machine, frontier API, provider server, private-cloud machine, on-premises server. Approval is configured by the organisation, not a certification; latency ordering is illustrative, not measured. Hard requirements always win.
UK · Organisation-managed · Standard model · Not on example ESG-approved list
UK · Organisation-managed · Standard model · On example ESG-approved list
UK · Organisation-managed · Standard + advanced model · Not on example ESG-approved list
Outside UK · Organisation-managed · Standard + advanced model · On example ESG-approved list
UK · External provider · Standard + advanced model · On example ESG-approved list
Outside UK · External provider · Standard + advanced model · Not on example ESG-approved list
Content analysis and policy checking happen inside Aventail™ Link. Aventail™ doesn’t need the query to make the routing decision.
Aventail™ Control distributes configuration ahead of time. Prompts and responses do not pass through the hosted Aventail™ Control service. Approved destinations receive the requests routed to them; frontier API calls use your own provider account. See how Aventail™ Link Server works for inference providers.
Aventail™ brings model deployment, execution, routing and management into one system. Aventail™ Link runs on your machines. Aventail™ Control manages them. Workspace gives your teams a place to use AI.
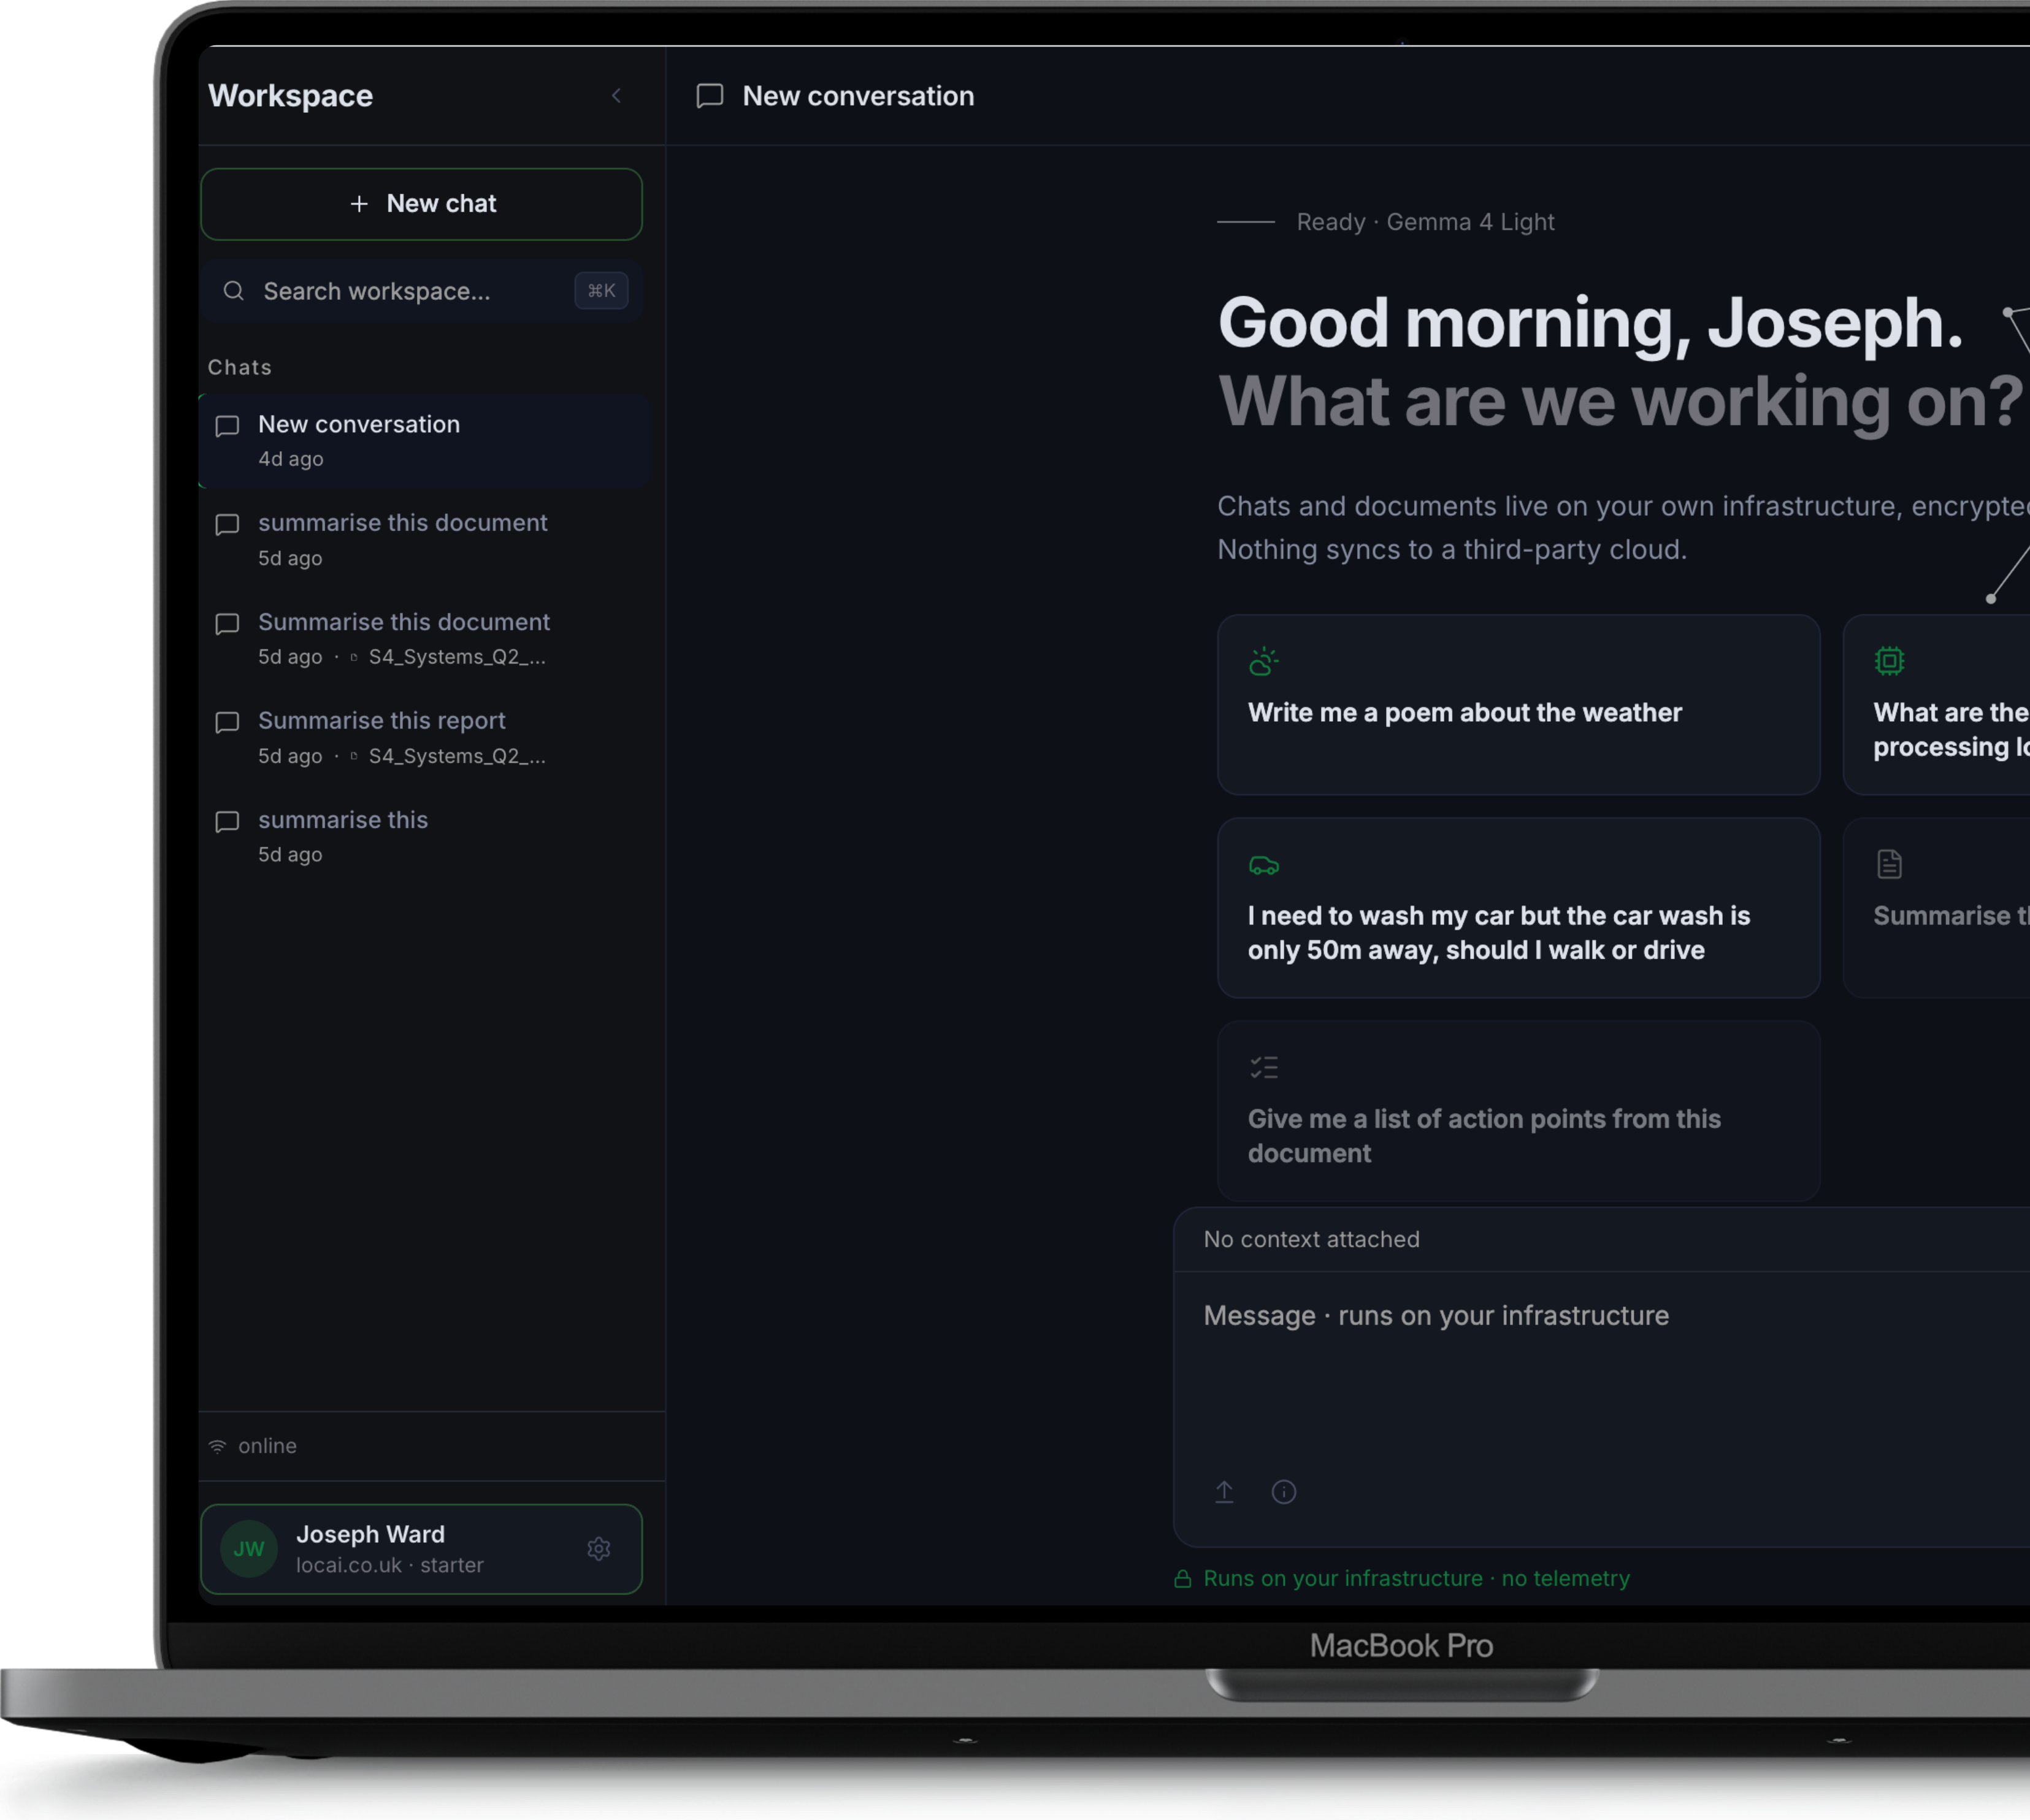
Manage machines, models and routing policies centrally. Distribute configuration to Aventail™ Link and review device and routing activity, outside the inference request path.
Install Aventail™ Link on supported hardware and deploy the model you want to run.
Choose allowed models, destinations and fallback paths in Aventail™ Control.
Aventail™ Link applies policy locally, then runs the request or sends it to an allowed destination.
Review the model, destination and routing rule in Aventail™ Control.
Keep sensitive work on approved infrastructure. Use your own hardware where it fits, and reach frontier APIs when your policy allows.
Choose where models can run and which destinations each workflow may use, including its fallback paths.
Run suitable workloads on hardware you already operate. Choose when a frontier model is worth using and keep external calls on your own provider account.
Review the model, destination and policy rule behind routing decisions, alongside device and routing events.
Begin with one workflow on your own infrastructure. Expand to other devices, private-cloud machines and approved providers as your requirements grow. Read the guide to keeping sensitive requests within approved infrastructure.
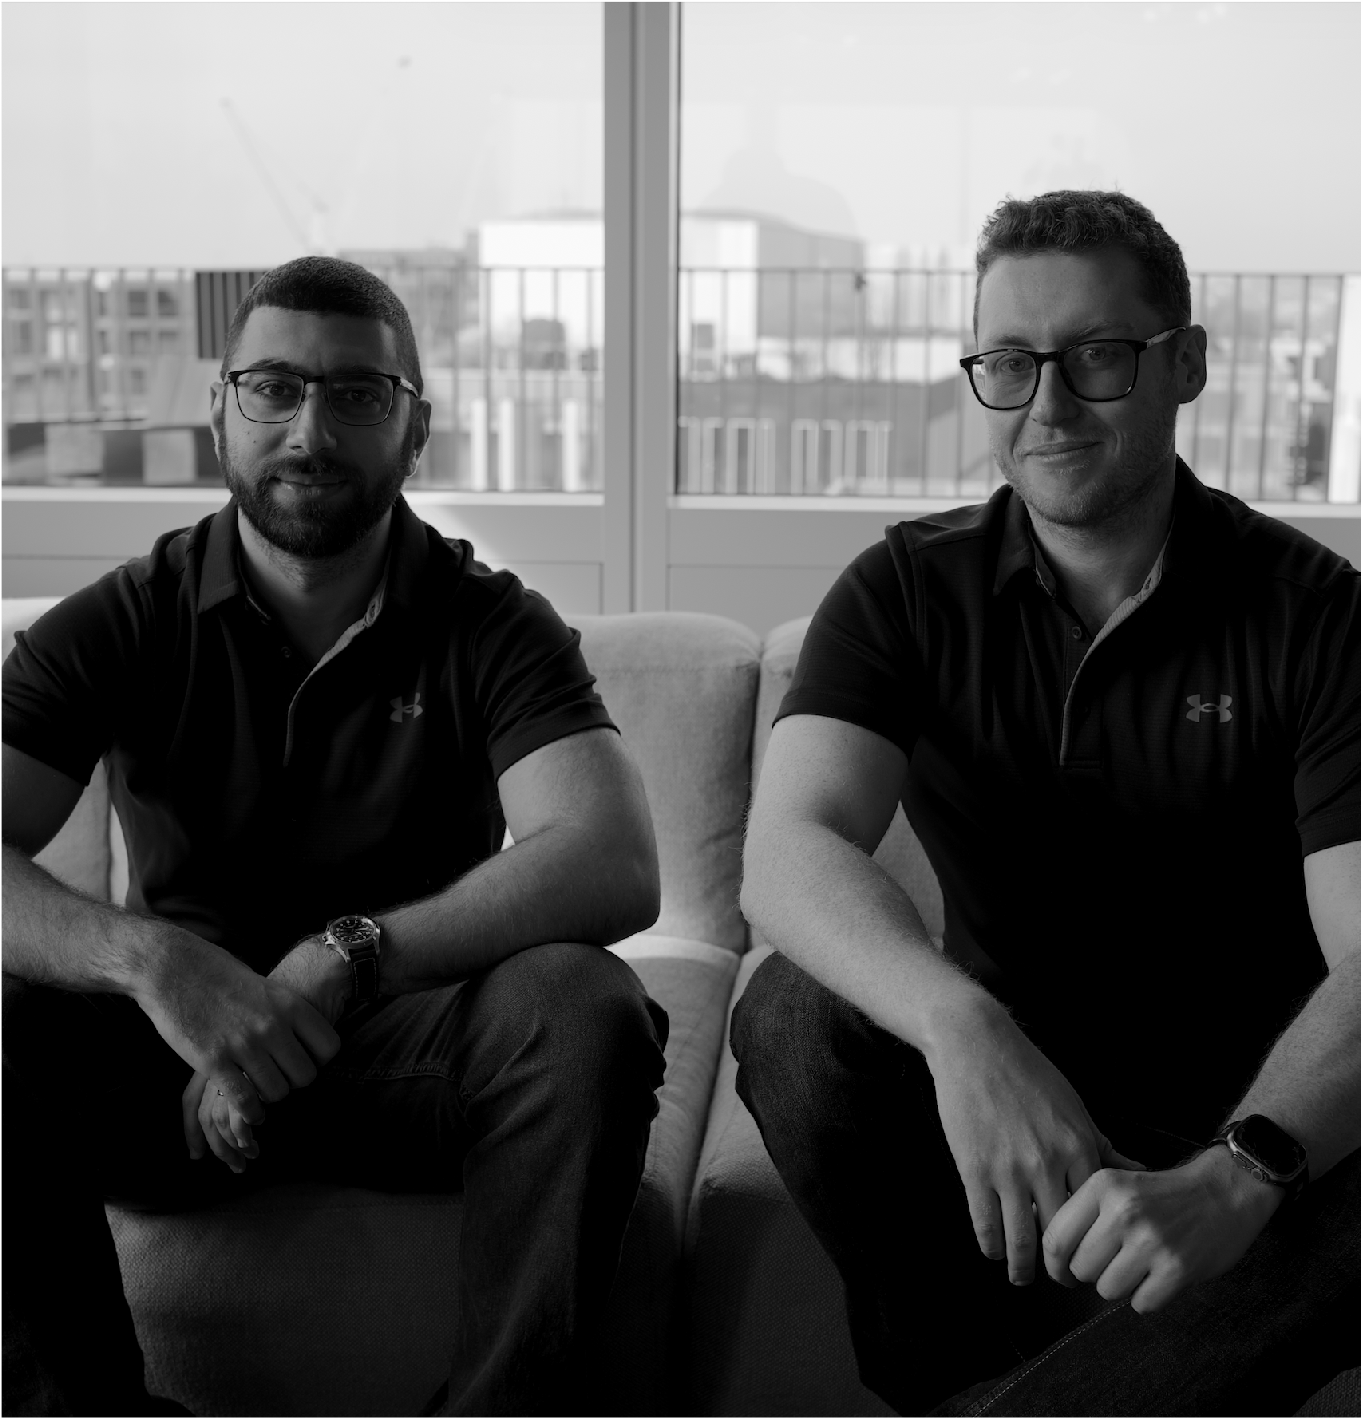
Saif Al-Ibadi and Joseph Ward have built production AI together since 2018, from neuromorphic computing to generative design for aerospace.
That experience shaped Aventail™: AI has to work with the hardware, connectivity and constraints in front of it.
An AI gateway or LLM router helps applications choose between model endpoints. Aventail™ also provides the runtime that deploys and executes supported models on your hardware. Aventail™ Link evaluates content and policy locally, then runs the request or routes it to another approved machine or frontier API. Aventail™ Control manages those machines outside the inference request path.
Yes. Aventail™ Link runs on your devices and servers, and Aventail™ Control may be hosted by Aventail™ or in your own estate.
The hosted Aventail™ Control service receives device and routing events, not prompts or responses. Aventail™ Link evaluates the applicable local policy on your machine.
Yes. Policy can route to a model on this device, another machine running Aventail™ Link or a frontier API through your own provider account. Local execution can continue offline when the required model is installed and your policy allows it. Remote machines and APIs require a connection.
Start with one useful workflow. Book a conversation with our team to discuss its requirements, your existing systems and the constraints that matter.
Bring one workflow, the hardware you have and the models you want to use. We’ll map where requests should run and what your first deployment needs.
We use optional cookies and tracking to identify visiting companies and load our contact form. Cookie policy